

2026 New AP-215 Exam Questions Real Salesforce Dumps
Course 2026 AP-215 Test Prep Training Practice Exam Download
NEW QUESTION # 35
A client has integrated data from Facebook Ads. Twitter ads, and Google ads in marketing Cloud intelligence. For each data source, the source, the data follows a naming convensions as ...
Facebook Ads Naming Convention - Campaign Name:
CampID_CampName#Market_Object#object#targetAge_TargetGender
Twitter Ads Naming Convention- Media Buy Name
MarketTargeAgeObjectiveOrderID
Google ads Naming Convention-Media Buy Name:
Buying_type_Market_Objective
The client wants to harmonize their data on the common fields between these two platforms (i.e. Market and Objective) using the Harmonization Center. Given the above information, which statement is correct regarding the ability to implement this request?
wet Me - Given the above information, which statement i 's Correct regarding the ability to implement this request?
- A. it is not possible to do this, as the naming conventions are different
- B. This is not possible as the naming conventions are in different fields (Campaign Name and Placement Name)
- C. The client will be able to do this and it will require building three patterns.
- D. The client Wi-Fi be able to harmonize only Google Ads and Twitter Ads, as Facebook Ads naming convention contains mufti delimiters.
Answer: C
Explanation:
Despite the different naming conventions, harmonization is possible using patterns in the Harmonization Center. By extracting the 'Market' and 'Objective' components from the naming conventions of each platform, three separate patterns would be created to map these common fields consistently across the data from Facebook Ads, Twitter Ads, and Google Ads.
NEW QUESTION # 36
Your client is interested in ingested the below file to a new generic data stream type:
The field 'Meeting Code' was mapped to the main entity key. 'How should the 'Room Number' be mapped?
- A. A custom metric and set aggregation to SUM
- B. A custom metric and set aggregation to AUTO
- C. An attribute of 'Meeting Code'
- D. A separate entity key
Answer: C
Explanation:
In Marketing Cloud Intelligence, when a field is mapped to the main entity key, other related fields should be mapped as attributes of that key if they provide additional descriptors or details. Since 'Room Number' is related to 'Meeting Code', it would be an attribute of the 'Meeting Code' entity, providing additional context to the meetings without serving as a metric or a separate entity key.
NEW QUESTION # 37
A client's data consists of three data streams as follows:
Data Stream A:
* The data streams should be linked together through a parent-child relationship.
* Out of the three data streams, Data Stream C is considered the source of truth for both the dimensions and measurements.
Assuming the data was ingested properly and the Parent Child was created correctly according to the client's requirements, what is the total Impressions value for Campaign Key 'CK_3'?
- A. 0
- B. 1
- C. 2
- D. N-A
Answer: C
Explanation:
Assuming that Data Stream A is set correctly with parent-child relationships:
To find the total impressions for Campaign Key 'CK_3', you would look in Data Stream A, since it contains the 'Impressions' metric.
As per the provided data, Campaign Key 'CK_3' has 100 impressions.
NEW QUESTION # 38
A client created a new KPI: CPS (Cost per Sign-up).
The new KIP is mapped within the data stream mapping, and is populated with the following logic: (Media Cost) / Sign-ups) As can be seen in the table below, CPS was created twice and was set with two different aggregations:
From looking at the table, what are the aggregation settings for each one of the newly created KPIs?
- A.

- B.

- C.

- D.

Answer: D
Explanation:
The KPI CPS (Cost per Sign-up) would be calculated by dividing the 'Media Cost' by 'Sign-ups'. The table indicates that CPS is set with two different aggregations. In option C, CPS #1 is set to 'AUTO', which allows the system to decide the best aggregation method based on the context. CPS #2 is set to 'SUM', which indicates that the individual costs per sign-up are summed up across multiple records to provide a total cost per sign-up.
NEW QUESTION # 39
Which three statements describe Overarching Entities? 03m 23s
- A. Some overarching entities hold a Many-to-Many relationship with the main entity, and others hold a One-to-Many relationship with it.
- B. These are mappable dimensions that are present in each and every dataset type
- C. When needed, these entities can act as a main entity, replacing the original one.
- D. The values of these entities are stored at the workspace level, rather than the data stream level
- E. Once the data streams in which Custom Classification values were mapped are deleted, their data is deleted.
Answer: A,C,D
Explanation:
Overarching Entities in Salesforce Marketing Cloud Intelligence are designed to provide a high level of data organization that spans across multiple data streams. The key points about Overarching Entities are:
B . Relationship Types: Overarching entities can have either a Many-to-Many or One-to-Many relationship with the main entity, which allows for flexible data modeling and relationship definitions based on the nature of the data and how it should be analyzed and reported.
C . Acting as Main Entity: They can serve as a main entity in certain situations, enabling a shift in perspective for data analysis. This can be particularly useful when there is a need to view data from a different dimension that is more aligned with business requirements.
E . Storage Level: The values of these entities are not tied to any single data stream but are maintained at a workspace level, ensuring that they can be applied consistently across different datasets, which is critical for maintaining data integrity and ensuring that classifications are applied uniformly.
NEW QUESTION # 40
A client has provided you with sample files of their data from the following data sources:
1.Google Analytics
2.Salesforce Marketing Cloud
The link between these sources is on the following two fields:
Message Send Key
A portion of: web_site_source_key
Below is the logic the client would like to have implemented in Datorama:
For 'web site medium' values containing the word "email" (in all of its forms), the section after the "_" delimiter in 'web_site_source_key' is a 4 digit number, which matches the 'Message Send Key' values from the Salesforce Marketing Cloud file. Possible examples of this can be seen in the following table:
Google Analytics:
Salesforce Marketing Cloud:
The client's objective is to visualize the mutual key values alongside measurements from both files in a table.
In order to achieve this, what steps should be taken?
- A. Within both files, map the desired value to Custom Classification Key as follows Salesforce Marketing Cloud: map entire Message Key to Custom Classification Key.
Google Analytics: map the extraction logic to Custom Classification Key. - B. Create a Web Analytics Site Source custom attribute and populate it with the extraction logic. Create a Data Fusion between the newly created attribute and the Message Send Key.
- C. Upload the two files and create a Parent-Child relationship between them. The Override Media Buy Hierarchy checkbox is checked in Google Analytics.
- D. Create a Web Analytics Site custom attribute and populate it with the extraction logic. Create a Data Fusion between the newly created attribute and the Message Send Key.
Answer: A
Explanation:
To create a linkage between Google Analytics and Salesforce Marketing Cloud data based on the "Message Send Key" and a portion of the "web_site_source_key," both values need to be harmonized into a common key. This is done by mapping the full Message Send Key from Salesforce Marketing Cloud and the extracted part of the web_site_source_key from Google Analytics to the same Custom Classification Key. This mapping will create a common identifier that can be used to combine the data from both sources for analysis and visualization.
NEW QUESTION # 41
A client wants to integrate their data within Marketing Cloud Intelligence to optimize their marketing insights and cross-channel marketing activity analysis. Below are details regarding the different data sources and the number of data streams required for each source.
What three advantages are gained when using Patterns & Data Classification as the harmonization method for creating the Objective field?
- A. Performance (Performance when loading a dashboard page)
- B. Scalability
- C. Use of code
- D. Processing (processing time when loading relevant data streams)
- E. Ease of Maintenance
Answer: A,B,E
Explanation:
Patterns & Data Classification in Marketing Cloud Intelligence offer several advantages. These include:
Ease of Maintenance (A): Patterns allow for the standardization of data harmonization processes. Once set up, they can be easily maintained and adjusted as needed, without having to manipulate each data stream individually.
Performance (B): By using patterns, data is classified and standardized at ingestion, which can improve the performance of dashboard page loading because the system does not need to perform complex, on-the-fly calculations or transformations.
Scalability (D): Patterns can be applied across multiple data streams consistently, allowing them to scale with the data. This means that as the amount of data grows or as new data sources are added, the same patterns can be reused, ensuring that the data remains harmonized.
NEW QUESTION # 42
A client's data consists of three data sources - Facebook Ads, LinkedIn Ads and Google Campaign Manager.
Notes:
* The client is planning on adding an additional 100 Facebook Ads data streams and 50 more LinkedIn Ads data streams.
* The final volume of data in the workspace will be 5M rows
* Each data source has a naming convention and it can be assumed that any additional profile (i.e. Data Stream) from one of these sources will follow the same naming convention.
The client provided the following sample files:
Facebook Ads:

The client would like to create a new harmonization field named "Market," which will only be coming from Facebook Ads and LinkedIn Ads. The logic for
"Market" is the following:
IF Media Buy Type is equal to "TypeB" or "TypeC" or "TypeD"
Return 'Europe'
ELSE
Return 'Rest Of The World'
In order to create the harmonization field Market, the client considers using either Mapping Formula, Calculated Dimension, VLOOKUP or Patterns.
Considering maintenance and scalability, which option is recommended?
- A. Patterns
- B. Calculated Dimension
- C. Mapping Formulas
- D. vLookuP
Answer: A
Explanation:
Patterns are the best approach in this scenario because:
Scalability: Patterns are highly scalable and can easily handle the addition of 100 more Facebook Ads and 50 more LinkedIn Ads streams. You can define pattern-matching rules that automatically apply to new data streams based on the naming conventions.
Flexibility and Maintenance: Patterns allow you to maintain and adjust logic easily. Since the logic for determining "Market" is based on a defined naming convention (e.g., Media Buy Type), Patterns can handle these rules effectively without requiring manual updates or static tables.
Efficient Harmonization: Patterns automatically classify data based on defined rules, reducing the need for ongoing manual maintenance compared to approaches like VLOOKUP or Mapping Formulas, which might require frequent updates as data changes.
Why not other options?
Mapping Formulas: While Mapping Formulas work well for static mappings, they are not as scalable or maintainable when the dataset grows or changes frequently.
Calculated Dimension: This option is valid for simple logic but is less maintainable for large-scale datasets, especially when new data streams are added.
VLOOKUP: This method is manual and not scalable. It would require you to update lookup tables for each new data stream, which is inefficient given the expected growth of the data.
NEW QUESTION # 43
A client's data consists of three data streams as follows:
Data Stream A:
The data streams should be linked together through a parent-child relationship.
Out of the three data streams, Data Stream C is considered the source of truth for both the dimensions and measurements.
The client would like to have a "Site Revenue" measurement.
This measurement should return the highest revenue value per Site, for example:
For Site Key 'SK_C_2', the "Site Revenue" should be $7.00.
When aggregated by date, the "Site Revenue" measurement should return the total sum of the results of all sites.
For example:
For the date 1 Apr 2020, "Site Revenue" should be $11.00 (sum of Site Revenue for Site Keys 'SK_C_1' ($4.00) and 'SK_C_2' ($7.00))
Which options will yield the desired result;
- A. Option #2 & Option #4
- B. Option #1 & Option #3
- C. Option #1 & Option #4
- D. Option #2 & Option #3
Answer: A
Explanation:
Option #2: It suggests using the 'SUM' function to aggregate the 'Site Revenue' for each 'Site Key'. This is necessary to ensure that when aggregated by date, 'Site Revenue' should return the total sum of the highest revenue for all sites.
Option #4: It indicates changing the Aggregation Function of Revenue to 'MAX' within Data Stream C.
This ensures that for a given 'Site Key', the highest revenue value is selected, which is correct for individual site revenue determination.
Combining Option #2 and Option #4 will provide the desired result:
For an individual 'Site Key', it will give the highest revenue (using MAX aggregation in Option #4).
When aggregating by date across all 'Site Key's, it will sum the highest revenues (using the SUM function in Option #2).
NEW QUESTION # 44
Which two statements are correct regarding the Parent-Child configuration?
- A. Parent-Child links different tables based on shared key values
- B. Parent-Child allows sharing both dimensions and measurements
- C. Parent-Child configurations can cause performances issues
- D. A Parent-Child cannot be configured between an Ads data stream type and a Conversion Tag one.
Answer: A,C
Explanation:
Parent-Child configurations in Marketing Cloud Intelligence are used to link different data tables based on shared key values, allowing for the relational organization of data across various streams. While this setup enhances data analysis and reporting by maintaining logical relationships between parent and child tables, it can also introduce performance issues. The complexity increases with the number of relationships and the volume of data, potentially slowing down query processing and data manipulation. Additionally, Parent-Child configurations facilitate the sharing of dimensions and measurements across linked tables, enhancing the data's usability without duplicating it.
NEW QUESTION # 45
A technical architect is provided with the logic and Opportunity file shown below:
The opportunity status logic is as follows:
For the opportunity stages "Interest", "Confirmed Interest" and "Registered", the status should be "Open".
For the opportunity stage "Closed", the opportunity status should be closed Otherwise, return null for the opportunity status
Given the above file and logic and assuming that the file is mapped in a GENERIC data stream type with the following mapping:
"Day" - Standard "Day" field
"Opportunity Key" > Main Generic Entity Key
"Opportunity Stage" - Generic Entity Key 2
"Opportunity Count" - Generic Custom Metric
A pivot table was created to present the count of opportunities in each stage. The pivot table is filtered on January (entire month). What is the number of opportunities in the Interest stage?
- A. 0
- B. 1
- C. 2
- D. 3
Answer: B
Explanation:
Based on the Opportunity file, the Opportunity Stage of 'Interest' occurs 3 times across unique Opportunity Keys. Since the pivot table is filtered to present the entire month of January and the Opportunity Stage 'Interest' is listed three times with different Opportunity Keys, the count of opportunities in the 'Interest' stage would be 3.
NEW QUESTION # 46
An implementation engineer has been asked to perform QA for a standard file ingestion, done by the client.
The source file that was ingested can be seen below:
The number of rows added to this data stream is 3. What could have led to this discrepancy?
- A. All fields are mapped except for the Media Buy Name.
- B. All fields are mapped except for the Creative Name
- C. All fields are mapped except for the Campaign Key
- D. All fields are mapped except for the Media Buy Key.
Answer: C
Explanation:
The source file shows data related to media buys, including a 'Media Buy Key', 'Media Buy Name', 'Campaign Key', and 'Site Key', among other fields. If only three rows were added, and the discrepancy is due to a missing field, it's likely that 'Campaign Key' is the field not mapped, because it is crucial for linking related records in the data stream. Without the 'Campaign Key', the system cannot associate the media buy data with specific campaigns, leading to a potential loss of data rows during ingestion.
NEW QUESTION # 47
Which three entities and/or functions can be used in an expression when building a calculated dimension?
- A. Calculated dimensions
- B. Mapped dimensions
- C. The EXTRACT function
- D. Mapped measurements
- E. The VLOOKUP function
Answer: B,C,D
Explanation:
Calculated dimensions (D) and the VLOOKUP function (A) are not typically used within the expression for a calculated dimension. Calculated dimensions are usually an output, not an input, and VLOOKUP is a function typically used to enrich or connect data, not within the definition of a calculated dimension itself.
Explanation:
In the context of Marketing Cloud Intelligence, when building a calculated dimension, you can typically use:
B). Mapped dimensions: These are dimensions that have been brought into Marketing Cloud Intelligence through the data integration process and have been mapped to a known schema or model.
C). The EXTRACT function: This function can be used to dynamically create dimensions by extracting values from a mapped dimension or measurement.
E). Mapped measurements: Similar to mapped dimensions, these are quantitative data points that have been integrated into the platform and can be referenced in calculations.
NEW QUESTION # 48
Your client provided the following sources:
Source 1:
Source 2:
Source 3:
As can be seen, the Product values present in sources 2 and 3 are similar and can be linked with the first extraction from 'Media Buy Name' in source1 The end goal is to achieve a final view of Product Group alongside Clicks and Sign Ups, as described below:
Which two options will meet the client's requirement and enable the desired view?
- A. Custom Classification: 1
Source 1: Custom Classification key will be populated with the extraction of the Media Buy Name.
Source 2: 'Product' will be mapped to Custom Classification key and 'Product Group' to a Custom Classification level. Exam Timer Source 3: 'Product will be mapped to Custom Classification key. Came - B. Overarching Entities:
Source 1: custom classification key will be populated with the extraction of the Media Buy Name.
Source 2: 'Product' will be mapped to Product field and 'Product Group' to Product Name.
Source 3: 'Product' will be mapped to Product field. - C. Parent Child:
All sources will be uploaded to the same data stream type - Ads. The setup is the following:
Source 1: Media Buy Key -- Media Buy Key, extracted product value - Media Buy Attribute.
Source 2: Product - Media Buy Key, Product Group -- Media Buy Attribute.
Source 3: Product - Media Buy Key. - D. Harmonization Center:
Patterns from sources 1 and 3 generate harmonized dimension 'Product'. Data Classification rule, using source 2, is applied on top of the harmonized dimension
Answer: A,D
Explanation:
To achieve a final view of Product Group alongside Clicks and Sign Ups, we should use:
Option A:
Custom Classification: By using a Custom Classification key populated with the extraction of the Media Buy Name in Source 1, we can then map 'Product' in Source 2 to this key and 'Product Group' to a Custom Classification level. This will allow for grouping and analysis by Product Group, as well as enable the desired view to be created.
Option D:
Harmonization Center: With patterns from Sources 1 and 3, we can create a harmonized dimension 'Product'. Then, by applying a Data Classification rule using Source 2, we can enhance the harmonized dimension. This allows us to align 'Product Group' with the 'Product' from Sources 1 and 3, facilitating an integrated view of Clicks and Sign Ups by Product Group.
NEW QUESTION # 49
A client would like to integrate the following two sources:
Google Campaign Manager:
IAS:
After configuring a Parent-Child relationship between the files, which query should an implementation engineer run in order to QA the setup?
- A. Media Buy Type, Media Buy Name, Impressions, Analyzed Impressions
- B. Creative Name, Impressions, Analyzed Impressions
- C. Media Buy Type, Analyzed Impressions
- D. Media Buy Name, Impressions
Answer: A
Explanation:
To QA the Parent-Child relationship setup between Google Campaign Manager and IAS data sources, it is essential to query fields that are common to both sources and that are relevant to the relationship. 'Media Buy Type' and 'Media Buy Name' are common identifiers between the two datasets. 'Impressions' from the Google Campaign Manager and 'Analyzed Impressions' from the IAS data are the metrics that should be compared to ensure they match or correlate as expected due to the Parent-Child relationship. The QA process involves checking that the data is correctly aligned and that the metrics from the parent source (Google Campaign Manager) are properly related to the metrics from the child source (IAS). Reference: Salesforce Marketing Cloud Intelligence documentation on data integration, Parent-Child relationships, and QA procedures for data setup.
NEW QUESTION # 50
A client's data consists of three data streams as follows:
Data Stream A:
* The data streams should be linked together through a parent-child relationship.
* Out of the three data streams, Data Stream C is considered the source of truth for both the dimensions and measurements.
How should the "Override Media Buy Hierarchies" checkbox be set in order to meet the client's requirements?
- A. It should be checked in Data Stream B
- B. It should be checked in Data Stream A
- C. It should not be checked in any of the three Data Streams.
- D. It should be checked in Data Stream C
Answer: D
Explanation:
If Data Stream C is the source of truth, the "Override Media Buy Hierarchies" checkbox should be checked for Data Stream C.
This means that the hierarchy defined within Data Stream C will take precedence over any other media buy hierarchies present in Data Streams A or B. By doing so, it enforces that the hierarchy from the source of truth (Data Stream C) is used throughout the dataset, maintaining the integrity of the hierarchical relationships as defined by the most reliable data source.
NEW QUESTION # 51
A client provides the following three files:
File A:
File B:
File C:
File A was uploaded using the Ads data stream type.
The client would like to create this view (data from Files B & C) in Datorama:
Which proposed solution would cause a false connection between the two files?
- A. Data Classification
- B. Custom classification
- C. VLOOKUP in Data Stream C. Vlookup will return "MB Name"
- D. VLOOKUP in Data Stream B. Vlookup will return "Day" and "Installs"
Answer: D
Explanation:
With File A uploaded using the Ads data stream type, the client wishes to create a view incorporating data from Files B & C.
A false connection would occur if VLOOKUP in Data Stream B is used incorrectly to return "Day" and "Installs". In this scenario, VLOOKUP might inaccurately link data based on MB Name between File B and File A or File C, which do not have a "Day" field to correctly join on. Moreover, "Installs" data in File B doesn't exist, so VLOOKUP cannot correctly return this information. The correct method would be to use the "Media Buy New Name" to link File B and File C since they both have this field, ensuring accurate connection and avoiding data mismatches or false connections.
NEW QUESTION # 52
Client has provided sample flies of their data from the following data sources:
Google Campaign Manager
Below are the requirements from the client and additional information:
* The sources are linked to each other by shared Media Buy names.
* In addition-to the mutual Media Buys, the sources contain campaign and site values. However, the client would like to see the campaign/site values coming from Google CM and not from Google DV360.
* The source of truth for cost is Google DV360.
As a first step, a Parent-Child relationship was created between the two files, and the following mapping was performed, within both data streams:
Please note:
* All other measurements were mapped as well to the appropriate fields.
* No other mapping manipulations or formulas were implemented.
How many records will the merged table hold?
- A. 0
- B. 1
- C. 2
- D. Depends on the Data Updates Permissions
Answer: A
Explanation:
Since the data sources are linked by shared Media Buy names and all other measurements are mapped to appropriate fields without additional manipulations, each unique Media Buy Name from Google DV360 will pair with its corresponding Media Buy Name in Google Campaign Manager. The number of records in the merged table will equal the number of unique Media Buy Names in Google DV360, provided there is a matching name in Google Campaign Manager. The sample shows 4 unique Media Buy Names in Google DV360, thus resulting in 4 records.
NEW QUESTION # 53
A client has integrated the following files:
File A:
File B:
The client would like to link the two files in order to view the two KPIs ('Tasks Completed' and 'Tasks Assigned) alongside 'Employee Name' and/or
'Squad'.
The client set the following properties:
+ File A is set as the Parent data stream
* Both files were uploaded to a generic data stream type.
* Override Media Buy Hierarchies is checked for file A.
* The 'Data Updates Permissions' set for file B is 'Update Attributes and Hierarchy'.
When filtering on the entire date range (1-30/8), and querying employee ID, Name and Squad with the two measurements - what will the result look like?
- A.

- B.

- C.

- D.

Answer: A
Explanation:
In Marketing Cloud Intelligence, when linking two data streams, the parent data stream (File A) provides the main structure. Since 'Override Media Buy Hierarchies' is checked for File A, the hierarchies from File B will be aligned with File A. Given 'Data Updates Permissions' set for file B as 'Update Attributes and Hierarchy', this means that attributes and hierarchy will be updated in the parent file based on the child file (File B), but the child file's metrics won't be associated with the parent file's date.
Hence, when filtering on the entire date range (1-30/8), the resulting view will align with the structure of the parent data stream, showing the KPIs ('Tasks Completed' from File A and 'Tasks Assigned' from File B) alongside the employee names and squads from the respective files. Since the employee IDs align, the data can be linked properly. However, since the dates do not align (File A data is from 01/08/2019 and File B from 15/08/2019), only attributes from File B will be updated without date association.
The result will look like Option C, where the employee names are corrected based on File B's data, the squads are added from File B, and the tasks_completed and tasks_assigned are displayed from their respective files. The tasks_assigned from File B are shown without date association as File B's date doesn't match with File A's.
NEW QUESTION # 54
A technical architect is provided with the logic and Opportunity file shown below:
The opportunity status logic is as follows:
For the opportunity stages "Interest", "Confirmed Interest" and "Registered", the status should be "Open".
For the opportunity stage "Closed", the opportunity status should be closed Otherwise, return null for the opportunity status.
Given the above file and logic and assuming that the file is mapped in a GENERIC data stream type with the following mapping
"Day" - Standard "Day" field
"Opportunity Key" > Main Generic Entity Key
"Opportunity Stage" - Main Generic Entity Attribute
"Opportunity Count" - Generic Custom Metric
A pivot table was created to present the count of opportunities in each stage. The pivot table is filtered on Jan 11th. What is the number of 'opportunities in the Confirmed Interest stage?
- A. 0
- B. 1
- C. 2
- D. 3
Answer: C
Explanation:
Based on the data provided and the date filter set to January 11th, there are no records for 'Confirmed Interest' on that specific date in the Opportunity file. Thus, the number of opportunities in the 'Confirmed Interest' stage for January 11th would be zero (0). In Salesforce Marketing Cloud Intelligence, when creating pivot tables, the data is aggregated based on the selected filters. If no records meet the filter criteria, the result for that category would be zero. The answer is supported by best practices in data analysis and reporting within Salesforce Marketing Cloud Intelligence, where date filters are applied to segment and analyze data.
NEW QUESTION # 55
The following file was uploaded into Marketing Cloud Intelligence as a generic dataset type: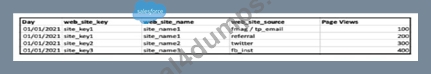
The mapping is as follows:
Day - Day
Web_site_source - Main Generic Entity Attribute 01
Page Views - Generic Metric 1
*Note that 'web_site_key' and 'web_site_name' are NOT mapped.
How many rows will be stored in Marketing Cloud Intelligence after the above file is ingested?
- A. 0
- B. 1
- C. 2
- D. 3
Answer: A
Explanation:
In Marketing Cloud Intelligence, when a file is uploaded as a generic dataset type and mapped accordingly, each unique combination of the mapped fields results in a separate row in the database. The file in question has been mapped with 'Day' to 'Day', 'Web_site_source' to 'Main Generic Entity Attribute 01', and 'Page Views' to 'Generic Metric 1'. The 'web_site_key' and 'web_site_name' are not mapped and thus, won't affect the row count.
Since there are 4 unique combinations of the mapped fields in the uploaded file (each day and source combination is unique), Marketing Cloud Intelligence will store 4 rows after ingestion, corresponding to each unique combination of 'Day' and 'Web_site_source'.
NEW QUESTION # 56
......
AP-215 Exam Info and Free Practice Test Professional Quiz Study Materials: https://www.actual4dumps.com/AP-215-study-material.html
Accurate Hot Selling AP-215 Exam Dumps 2026 Newly Released: https://drive.google.com/open?id=1upl3R7BerZtr7Di7HmQnh-eGn5t6kmIe